AI from First Principles · Week 06 Revisited
I’ll be honest up front: this is the topic I’m most excited about in the whole course. Here’s why Week 06 matters, what the results tell us, what they don’t — and an open invitation at the end for students who want to work on it with me.
Session date: 7 October 2026 · Week 06 on the MSNM course page
From data-driven to physics-informed
For five weeks, every network we built learned the same way: give it inputs, give it the right answers, and let it close the gap. In Week 04, for example, the CNN surrogate needed 5,000 FE solutions before it could predict anything.
Week 06 flipped that around. A Physics-Informed Neural Network (PINN) doesn’t need a dataset of solutions at all. Instead, the governing equation, boundary conditions and initial conditions go straight into the loss function. The network is penalised whenever it breaks the physics, not whenever it disagrees with a label.
For anyone who has spent years writing FEM or meshfree codes, that should sound very familiar. And that’s exactly why I find it so interesting.
The problem
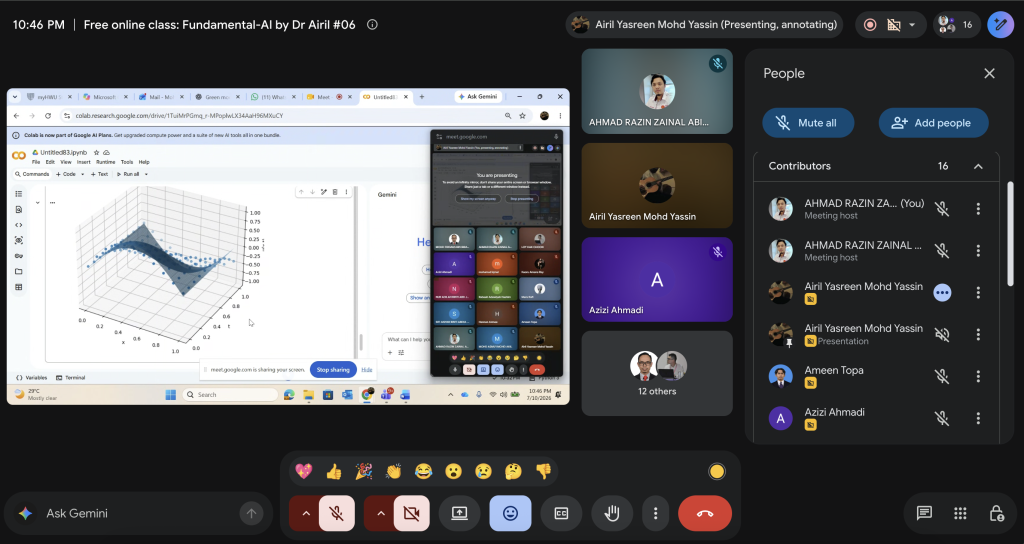
We used the classic one-dimensional wave equation, kept in dimensional (unscaled) form on purpose for Part A:
∂²u/∂t² − c² ∂²u/∂x² = 0
with fixed ends, u(0,t) = u(1,t) = 0, and a string released from rest in its first mode, u(x,0) = sin(πx) and ∂u/∂t(x,0) = 0. With L = c = A = 1, the analytical solution is simply u = sin(πx) cos(πt), so we always know exactly how wrong the network is.
The network itself is as small as it gets: inputs x and t, one hidden layer of m tanh neurons, and a single output:
û(x,t) = Σj=1m vj tanh(w2j−1x + w2jt + bj)
What I really liked
1. Everything by hand. No autodiff, no PyTorch.
This is the part that makes the course unusual. Every derivative of the network, every residual, and all twelve loss gradients (four parameter types × three losses) were derived on paper first, then coded line by line in NumPy with the equation numbers written next to each line. No loss.backward() hiding anything.
It’s slow, and it’s meant to be. Once you’ve derived ∂LD/∂bk yourself and seen the third derivative of tanh appear in it, you understand why PINNs are expensive in a way no tutorial can teach you.
2. “The derivative of a network is just another network”
This was my favourite moment. Dr. Airil drew the derivatives as four networks — A, B, C and D — sharing exactly the same inputs and hidden layer. The only things that change are the activation and the output weights:
| Network | Computes | Hidden activation | Output weight |
|---|---|---|---|
| A | û | σ | vj |
| B | ∂û/∂t | σ′ | vjw2j |
| C | ∂²û/∂x² | σ″ | vjw2j−1² |
| D | ∂²û/∂t² | σ″ | vjw2j² |
So the domain residual is just RD = Network D − c² × Network C, evaluated at a collocation point. Once you see it drawn this way, it’s hard to un-see.
3. It looks a lot like our own methods
This is where my own research brain switched on. Put the PINN next to things we already know:
- û = Σ vj σj reads just like u = Σ Ni di. The vj play the role of nodal unknowns, and the tanh neurons act like basis functions — except their shape and position (w, b) are trained too. An adaptive basis.
- Enforcing the PDE at scattered points (xi, ti) is strong-form point collocation, the same family as collocation meshfree methods.
- Adding the boundary residuals to the loss is essentially a penalty method for BCs — soft enforcement, not exact.
Those connections aren’t just cute analogies. Strong-form collocation and penalty-type BC enforcement both come with well-known weaknesses, especially near boundaries. Which brings me to the results.
So how did it do?
Training used 1,000 random domain points, 100 points on each boundary, 100 initial-condition points, a learning rate of 0.0005, and a simple SGD-like scheme that updates the parameters after every single point. Here’s what the snapshot at t = 0.25 showed, read from the plots in the note:
| m | Epochs | Interior | û(1, 0.25) (exact = 0) |
|---|---|---|---|
| 5 | 1,000 | Almost flat — fails | ≈ 0.30 |
| 10 | 2,500 | Close, slightly low at peak | ≈ 0.13 |
| 20 | 5,000 | Very close | ≈ 0.09 |
| 50 | 10,000 | Practically on top | ≈ 0.05 |
Approximate values read from Figure 12 of the note. Peak displacement at t = 0.25 is about 0.71, so the m = 10 boundary error is roughly 18% of the peak.
The trend is exactly what you’d hope for: more neurons and more epochs, and the PINN converges towards the analytical solution. Getting there with a from-scratch NumPy code and no data at all is genuinely satisfying.
But look at the last column. Even at m = 50, the right-hand end still isn’t pinned at zero, while the left end behaves nicely. That asymmetry is the most interesting thing in the whole session, and I don’t think we know yet why it happens.
What the results don’t show yet
Again, not a criticism — Part A was designed to be transparent, not optimal. But these are the questions I’d want answered before trusting a PINN on a real engineering problem:
- Why is the right boundary worse? A few candidate explanations: the domain loop does 1,000 updates per epoch against only 200 boundary updates, so the PDE “outvotes” the BCs; the fixed loop order (domain → boundary → initial) means the IC updates always get the last word each epoch; or something about how tanh neurons initialised around the origin reach x = 1. These are hypotheses, not findings. Each one is testable.
- The BCs are only approximately satisfied. That’s the price of penalty-type enforcement. An alternative is to build the BCs into the trial function, for example û = x(1 − x) N(x,t), so they hold exactly. It changes every gradient, but it removes a whole loss term.
- No error norm yet. We compared plots, not numbers. A relative L2 error over the x–t domain would let us talk about convergence rates, not just “it gets closer”.
- No cost comparison. A finite difference scheme solves this problem to high accuracy in a fraction of a second. For forward problems like this one, the PINN isn’t competing on speed. Its real strengths lie elsewhere — inverse problems, sparse measured data, and mesh-free handling of awkward geometries.
- One smooth mode, one time window. The solution is a single sine mode over t ∈ [0, 1]. Higher modes, sharper features, or predicting beyond the training time window are all known to be much harder for PINNs.
Part B will tackle some of these directly: nondimensional equations, weighted and normalised losses, deeper networks and automatic differentiation. Keep an eye on the course page for it.
Try it yourself: three small experiments
- Gradient check. Hand-derived gradients deserve verification. Compare one of them against a finite-difference estimate (snippet below). If they agree to several digits, you can trust the other eleven a lot more.
- More boundary points. Raise
n_Bfrom 100 to 500 and see whether the right-end error shrinks. If it does, the “PDE outvotes the BCs” hypothesis gains some weight. - Change the loop order. Run the boundary loop last instead of the initial-condition loop. Does the asymmetry move?
# Finite-difference check of dL_D/dv_k at one domain point
def domain_loss(w, b, v, x, t, c=1.0):
    wx, wt = w[0::2], w[1::2]          # w[2k] -> x, w[2k+1] -> t
    s = np.tanh(wx*x + wt*t + b)
    s2 = -2.0*s*(1.0 - s**2)           # second derivative of tanh
    uxx = np.sum(v*wx**2*s2)           # Network C
    utt = np.sum(v*wt**2*s2)           # Network D
    return (utt - c**2*uxx)**2, utt - c**2*uxx, s2

x_i, t_i, k, eps = 0.3, 0.4, 2, 1e-6
L0, R_D, s2 = domain_loss(w, b, v, x_i, t_i, c)
wx, wt = w[2*k], w[2*k+1]
g_hand = 2*R_D*(wt**2 - c**2*wx**2)*s2[k]          # Eq. (45)

vp, vm = v.copy(), v.copy(); vp[k] += eps; vm[k] -= eps
g_fd = (domain_loss(w, b, vp, x_i, t_i, c)[0]
        - domain_loss(w, b, vm, x_i, t_i, c)[0]) / (2*eps)
print(f"hand = {g_hand:.8e}, FD = {g_fd:.8e}, rel diff = {abs(g_hand-g_fd)/abs(g_fd):.2e}")
Students: want to do research on PINNs? Talk to me.
PINNs sit right where my own work lives — computational mechanics, FEM and meshfree methods — and I’m actively looking for students who want to dig into them. Final-year projects, MSc and PhD are all welcome. Some directions I’d love to explore:
- PINNs vs. meshfree collocation — what can each learn from the other, especially on boundary accuracy?
- Exact vs. penalty-type BC enforcement — and the loss-balancing problem that comes with it.
- PINNs for structural mechanics — beams, plates and elasticity, where fourth-order equations make things far more interesting.
- Inverse problems — identifying stiffness, damage or material parameters from limited measurements.
- Energy-based and hybrid FEM–PINN formulations — bringing the weak form back into the picture.
You don’t need to be an AI expert already. Comfort with calculus, some Python, and real curiosity are enough — this course is the best possible starting point. Email me with a short note about yourself and what caught your interest.
Week 06 materials — all open
- Note (Week 06) ↗ — the annotated class note
- Module: PINN Part A ↗ — full derivations, gradients and NumPy code
- Recorded Video, Part 1 ↗ — forward pass, network derivatives and residuals
- Recorded Video, Part 2 ↗ — gradients, the training loops and results
- AI Learning Modules ↗ — all course modules on the MSNM GitHub
New to the course? Start from Week 01 — the backpropagation in Week 02 is exactly what Week 06 builds on. The class is free and runs online every Tuesday, 9:00–11:00 PM (Malaysia time); you can register here and join the WhatsApp group.
Thanks to Dr. Airil for a session that was genuinely hard work to follow and worth every minute, and to everyone who stuck with twelve hand-derived gradients late on a Tuesday night. If you try any of the experiments above, share your results in the WhatsApp group — especially if you crack the right-boundary puzzle.
See you in class!
Dr. Ahmad Razin Zainal Abidin
Faculty of Civil Engineering, UTM · Malaysian Society for Numerical Methods
Recent Comments