AI from First Principles · Week 04 Revisited
It has been almost two months since Week 04, and I still keep coming back to it. So here are my thoughts — what I enjoyed, what the results actually tell us, and what they don’t tell us yet.
Session date: 25 August 2026 · Week 04 on the MSNM course page
Why this session stuck with me
Of the six sessions of AI from First Principles so far, Week 04 is the one that felt closest to home for those of us in computational mechanics. Most CNN examples we see are about cat photos, MNIST digits or faces. This time, the input was a stiffness matrix.
And once the input is something we understand from the inside, the questions change. It’s no longer just “what’s the R²?” but “does the model actually understand the structure of this matrix, or is it just a very good guesser?”
This isn’t an official summary — it’s my own notes after a few weeks of thinking about it. If you attended, treat it as the after-class discussion we never quite had time for. If you haven’t joined yet, I hope it gives you a feel for what the class is really like. Links to the note and recordings are at the end.
What we did that night
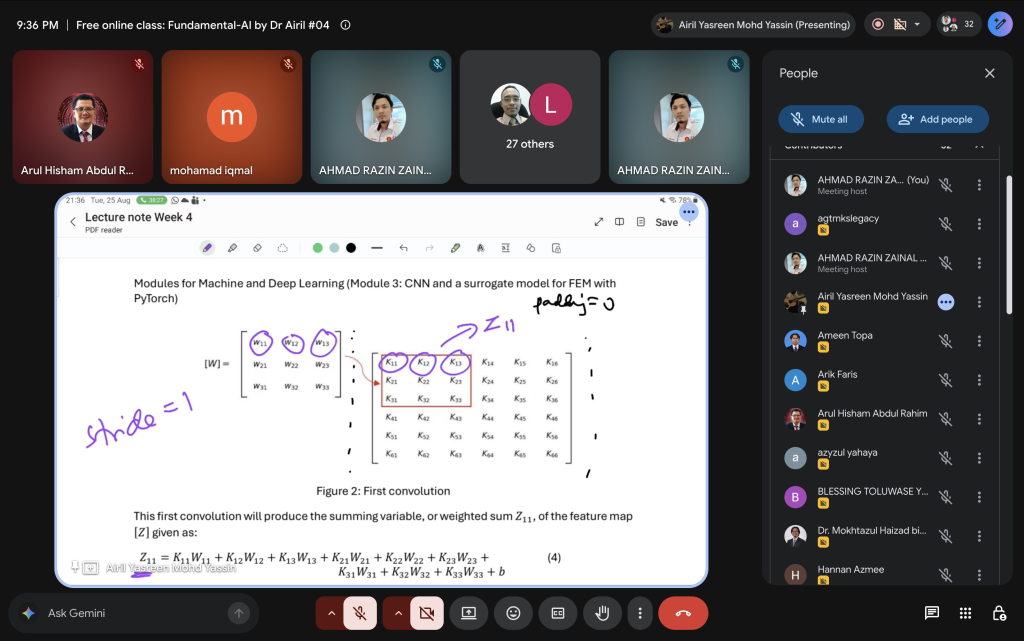
As in the earlier weeks, Dr. Airil stuck to the same rule: derive it by hand first, then let PyTorch automate it. The architecture looks roughly like this — [K] goes through the convolution path, while {F} skips the queue and goes straight into the FFNN:
[K] 6×6 → Conv 3×3 (stride 1) → [Z] 4×4 → tanh → [A] 4×4 → MaxPool 2×2 → [P] 2×2 → flatten 4×1 → + {F} 6×1 → FFNN 10→32→6 → {U} 6×1
The problem was kept deliberately small: a simply supported beam with three Euler–Bernoulli elements, each with its own I1, I2, I3 and q1, q2, q3. After removing the restrained DOFs at the supports, six remain — the two end rotations and the deflection–rotation pairs at the two interior nodes. So the system is
[K̄]6×6 {Ū}6×1 = {F̄}6×1
Solve that 5,000 times with random parameters and you get 5,000 labelled pairs ([K̄], {F̄}) → {Ū}: 70% for training, 30% for validation. Simple, but enough to see every important piece.
What I really liked
1. The convolution was written out, not just described
Before PyTorch showed up at all, we wrote out the first entry of the feature map term by term:
Z11 = K11W11 + K12W12 + K13W13 + K21W21 + K22W22 + K23W23 + K31W31 + K32W32 + K33W33 + b
Written this way, you immediately go “hang on, that’s just the summing variable Z from the FFNN in Module 1.” A weighted sum plus a bias. Only two things differ: the inputs come from a small 3×3 patch of a matrix instead of a column vector, and the same nine weights are reused at every kernel position. For FEM people, this makes far more sense than the usual “the filter detects edges” story.
2. Weight sharing came with numbers
To produce the 16 entries of the 4×4 feature map, the convolutional layer needs only 3×3 + 1 = 10 parameters. A plain dense layer connecting all 36 entries of [K] to 16 neurons would need (36×16) + 16 = 592. That’s a saving of about 1 − 10/592 ≈ 98.3%. Don’t take my word for it — count it yourself.
A nice small exercise for students is to do the same count for the whole model:
| Layer | Shape | Weights | Biases | Total |
|---|---|---|---|---|
| Conv2d | 1 → 1, 3×3 | 9 | 1 | 10 |
| fc1 | 10 → 32 | 320 | 32 | 352 |
| fc2 | 32 → 6 | 192 | 6 | 198 |
| Model | 560 |
Notice that the convolutional part is less than 2% of the whole model. Keep that in mind — we’ll come back to it.
3. The stiffness matrix was treated as something with structure
The most interesting argument in the note, for me: for a fixed DOF ordering, where an entry sits in the stiffness matrix tells you something about element connectivity — just as in a photo of a face, the left eye really is next to the left ear. You can see it straight from the data: K14, K15 and K16 are zero in every single sample, because those DOFs share no element. The matrix is banded, and a 3×3 kernel sliding along it keeps seeing the coupling blocks left behind by nodal assembly.
4. Good data habits from the start
The MinMaxScaler was fitted on the training set only, then applied to the validation set, and the predictions were inverse-transformed back to physical units before computing the metrics. Small details — but exactly the ones that quietly make results look better than they are when skipped.
So how did it do?
One hidden layer, Adam at a learning rate of 0.001, 5,000 epochs, no hyperparameter tuning at all. On the 1,500 validation samples:
| Output | R² | RMSE | MAE |
|---|---|---|---|
| U1 | 0.8772 | 6.16e-3 | 4.46e-3 |
| U2 | 0.9433 | 6.99e-3 | 5.11e-3 |
| U3 | 0.9525 | 2.74e-3 | 1.83e-3 |
| U4 | 0.9627 | 5.66e-3 | 4.08e-3 |
| U5 | 0.9701 | 2.17e-3 | 1.58e-3 |
| U6 | 0.9380 | 4.35e-3 | 3.01e-3 |
Validation metrics in physical units, from the Week 04 note. U1 is highlighted because it’s the weakest.
For an untuned model with a single kernel, that’s a decent result, and the scatter plots in the note show the points sitting close to the 45° line for all six DOFs.
But… what the results don’t show yet
This is the part I’ve enjoyed thinking about most. It’s not a criticism of the session — a first CNN module should be small and transparent. But if we sent these results to a reviewer, these questions would come up for sure. Better we ask them ourselves first:
- The surrogate isn’t faster than its solver. Solving a 6×6 system is practically free. The point here is to show the network can learn the mapping ([K], {F}) → {U}, not to speed it up. Surrogates earn their keep when the forward model is expensive: large meshes, nonlinear materials, transient analysis, or thousands of evaluations inside an optimisation loop.
- Predictions aren’t checked against equilibrium. R² only tells us how close we are to the FE answer, not whether the displacements actually satisfy the governing equation. The simplest check is the relative residual r = ‖[K̄]{Upred} − {F̄}‖ / ‖{F̄}‖ — one matrix–vector product per sample. And if you put that residual straight into the loss function… well, that’s the idea behind the PINNs we started in Week 06.
- “Spatial” depends on DOF numbering. Renumber the DOFs and the rows and columns of [K] get shuffled — same physics, different “picture” for the kernel. So the convolution is exploiting a convention, not an invariant. Fine for a fixed mesh; a problem once you want to transfer to another discretisation.
- The input size is locked to the mesh. The model only accepts a 6×6 matrix. A four-element beam gives an 8×8 system and needs a new network. Generalising across meshes is still an open research question.
- The convolution path is narrow. Remember the 2%? Thirty-six stiffness entries are squeezed into four numbers by one kernel and one max operation, while all six entries of {F} go straight into the FFNN. It’s quite possible that most of the predictive work is being done by {F} and the dense layers. Honestly, I don’t know — but an ablation would tell us.
- U1 deserves a closer look. The left-end rotation is consistently the weakest. Is it the sampling range of the parameters, pooling throwing away information that matters for that DOF, or just not enough training? No answer yet.
- This is interpolation, not extrapolation. Validation samples come from the same distribution of Ii and qi as the training data. The metrics say nothing about performance outside that range.
The session showed that a CNN can learn an FEM mapping. The more interesting question — is the convolution really using the structure of the stiffness matrix? — is now something every participant can test.
Try it yourself: four small experiments
If you still have the Week 04 notebook in Colab, each of these is a few lines of change. I think you’ll learn more about the model from them than from staring at R²:
- Ablation. Replace [K] with a constant matrix (or zeros) and retrain. If R² barely moves, the convolution isn’t contributing much.
- Permutation. Apply the same DOF shuffle to every [K], {F} and {U} and retrain. Does the CNN care?
- Width. Raise
out_channelsfrom 1 to 4 or 8 (remember to fix the input size offc1) and see whether U1 improves. - Equilibrium check. Compute the residual r for every validation sample and plot its distribution next to R².
# Equilibrium residual on the validation set (physical units)
K_val_mat = K_val.reshape(-1, 6, 6)
R = np.einsum('nij,nj->ni', K_val_mat, U_val_pred) - F_val
r = np.linalg.norm(R, axis=1) / np.linalg.norm(F_val, axis=1)
print(f"median r = {np.median(r):.3e},  max r = {r.max():.3e}")
If you try any of these, please share your results in the WhatsApp group. I genuinely want to know.
A quick note on notation: the lecture note writes [K̄]{Ū} = {F̄}, where the bar marks raw data before normalisation. The course page summary uses {D} for the displacements. Same thing — don’t let it confuse you.
Week 04 materials — all open
- Note (Week 04) ↗ — Module 3: CNN and a surrogate model for FEM with PyTorch
- Recorded Video, Part 1 ↗ — the maths of convolution, activation, pooling and flattening
- Recorded Video, Part 2 ↗ — building and training the CNN+FFNN surrogate in PyTorch
- CNN_FEM_beam_K_F_to_U_5000.csv ↗ — the 5,000 beam samples we used
- AI Learning Modules ↗ — all course modules on the MSNM GitHub
- Week 04 on the MSNM site ↗ — session summary and the full course archive
Where we went after Week 04
Next came Week 05 on Recurrent Neural Networks, with a flood-routing example and time-dependent data, and then Week 06 on PINNs (Part A), where the physics goes straight into the loss function — the natural answer to the equilibrium question above. If you’re new, I’d suggest starting from Week 01; each week builds directly on the maths of the one before.
Come join us — it’s free and open to everyone
AI from First Principles by Dr. Airil Yasreen Mohd Yassin runs online every Tuesday, 9:00–11:00 PM (Malaysia time). It’s for students, researchers, lecturers, engineers and industry folks who want to understand the maths behind AI rather than use it as a black box. Every session is recorded, and all notes and modules stay open.
Thanks to Dr. Airil for leading the session, to my fellow module authors — Dr. Hirol, Dr. Mokhtaram and Dr. Mohd Noor — and to everyone who stayed until the very end of a late Tuesday night. Comments, corrections, or results from the experiments above? Drop them in the WhatsApp group or email admin@msnm.com.my.
See you in class!
Dr. Ahmad Razin Zainal Abidin
Faculty of Civil Engineering, UTM · Malaysian Society for Numerical Methods
Recent Comments